Course map · S1 How LLMs work · Episode 5 of 12
The transformer
Lesson complete
The transformer
The rule to keep
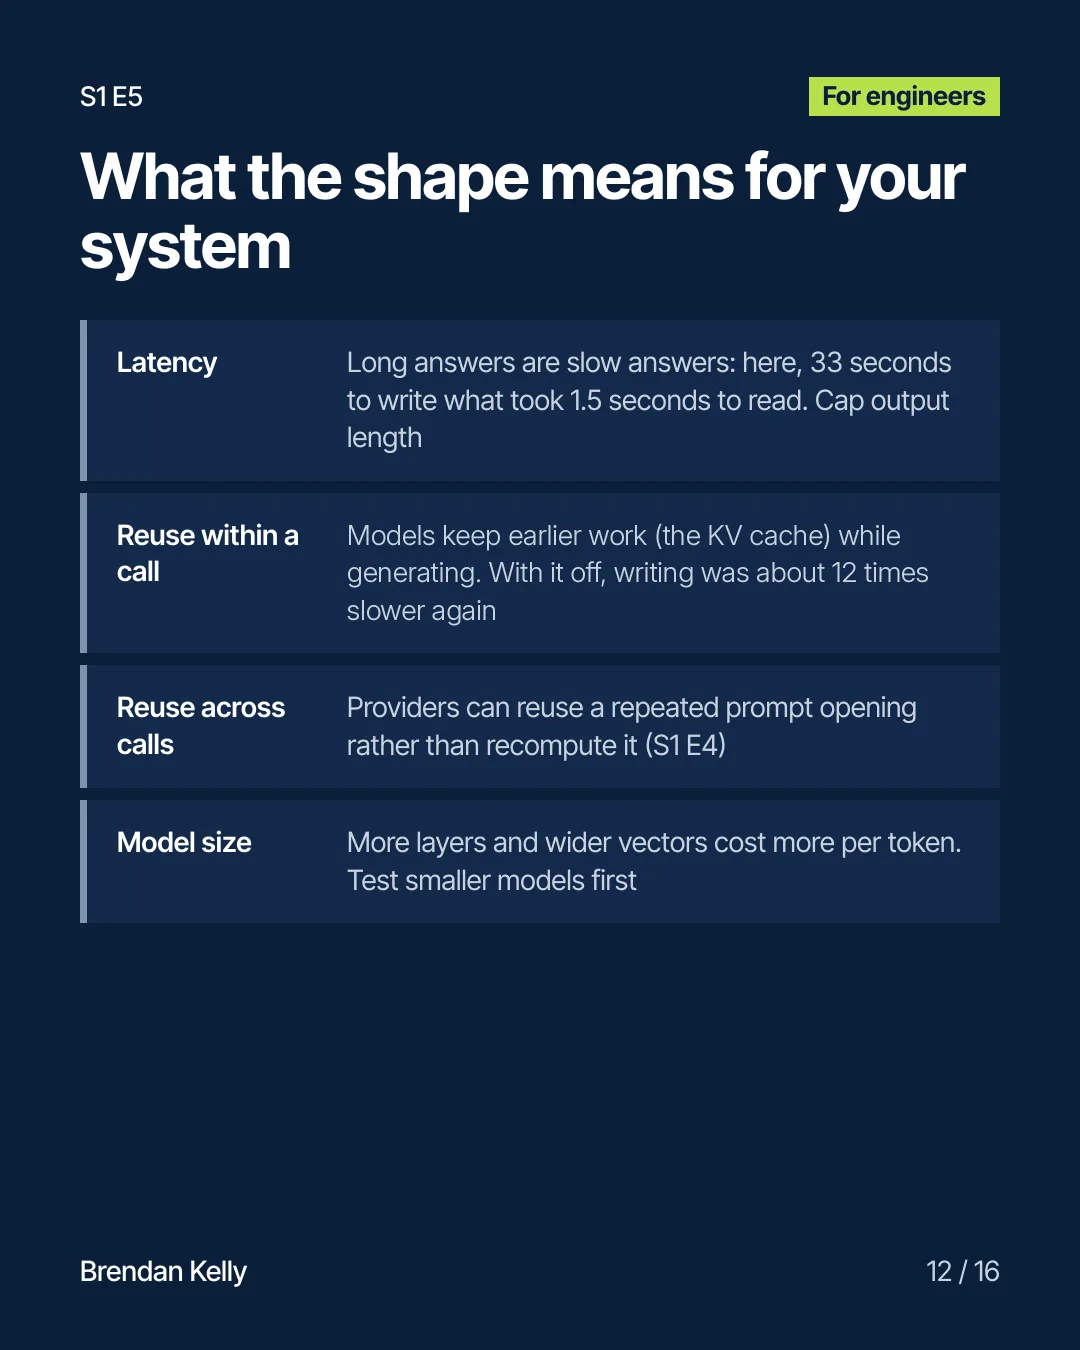
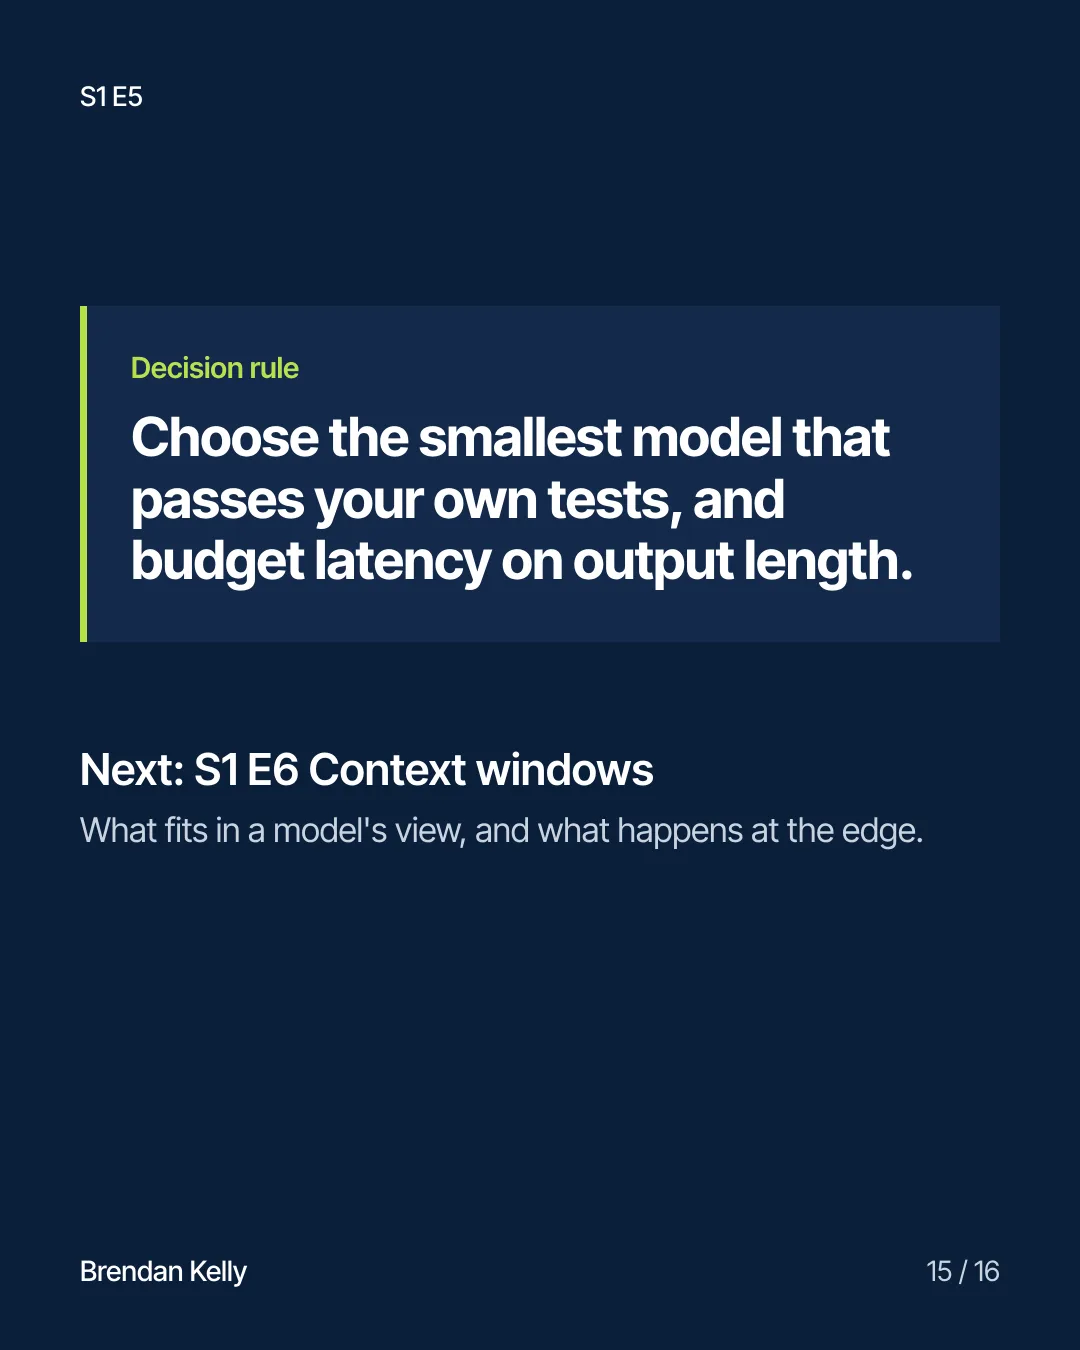
Choose the smallest model that passes your own tests, and budget latency on output length.
1 / 16
Lesson notes
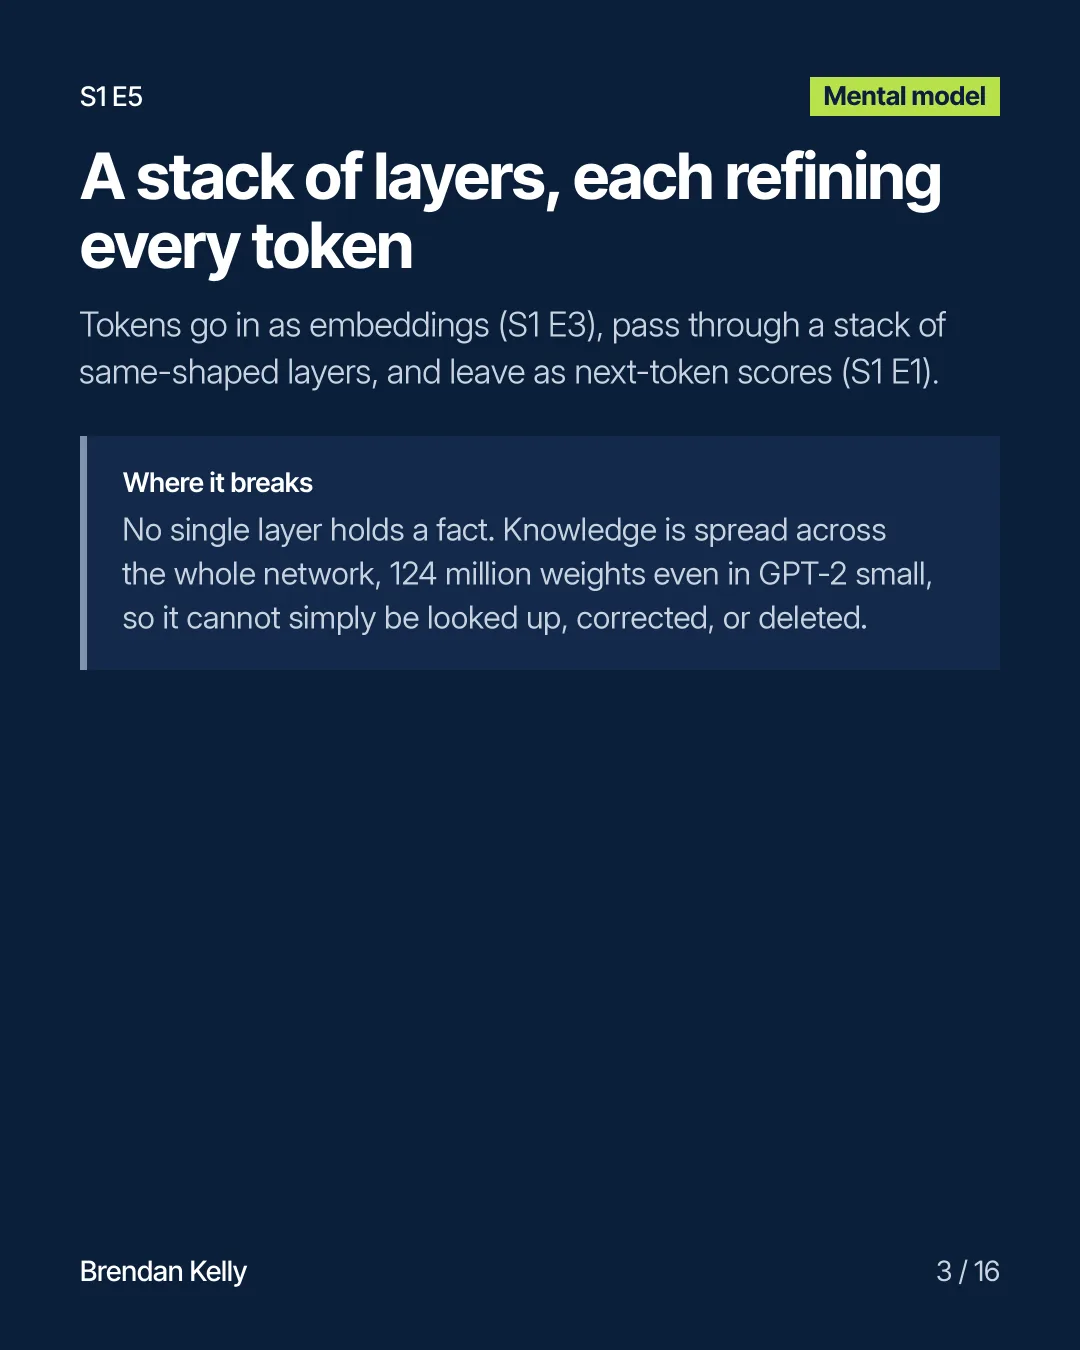
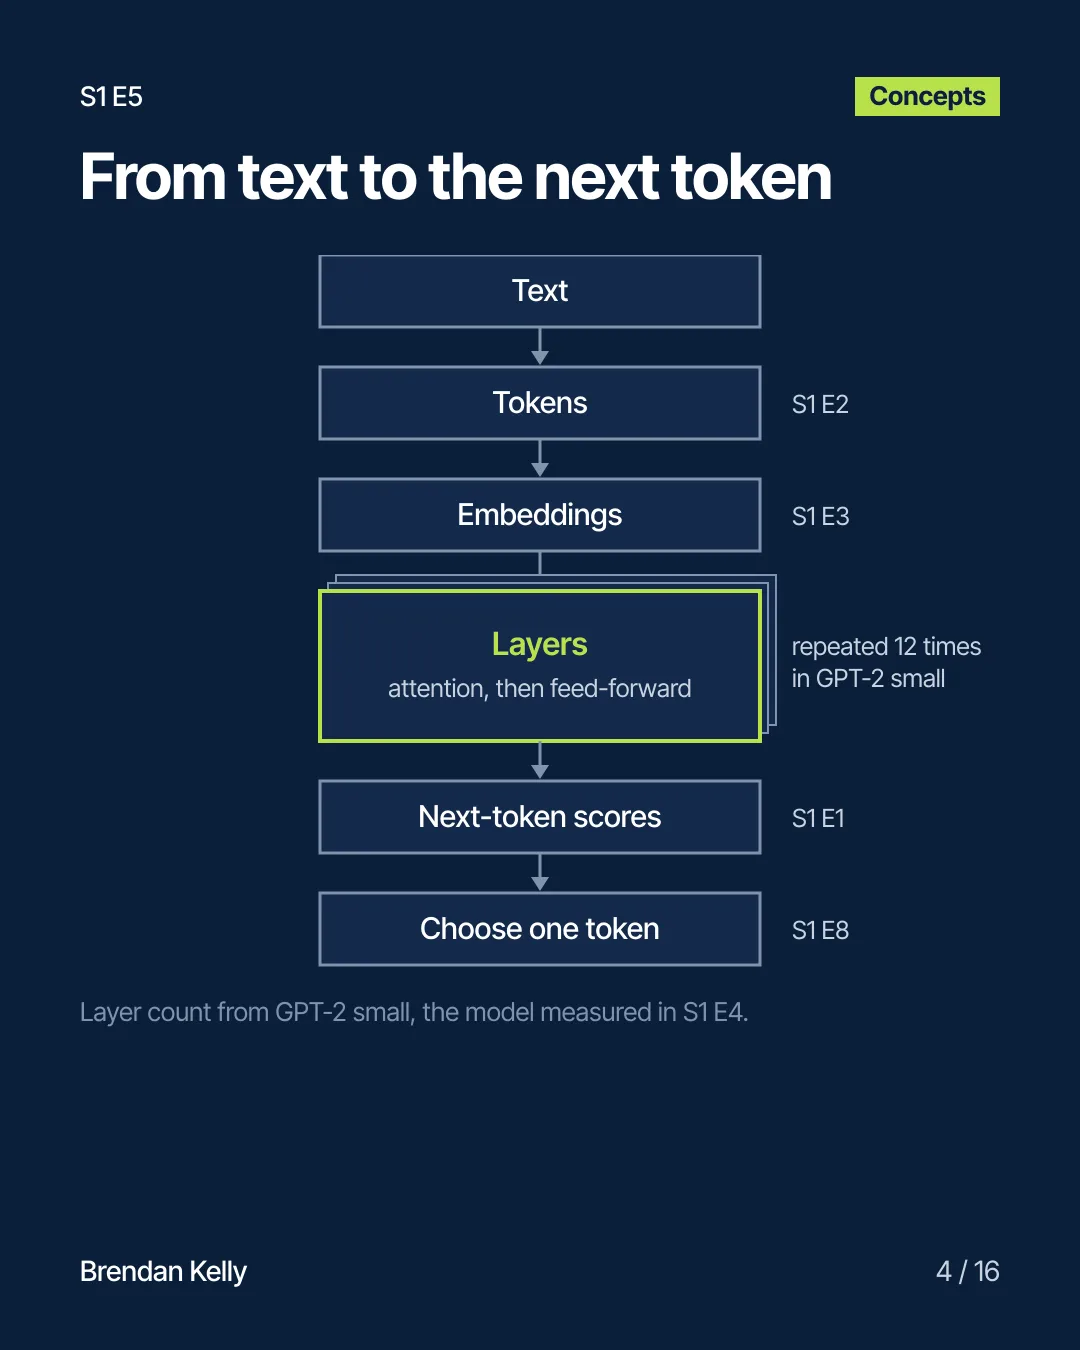
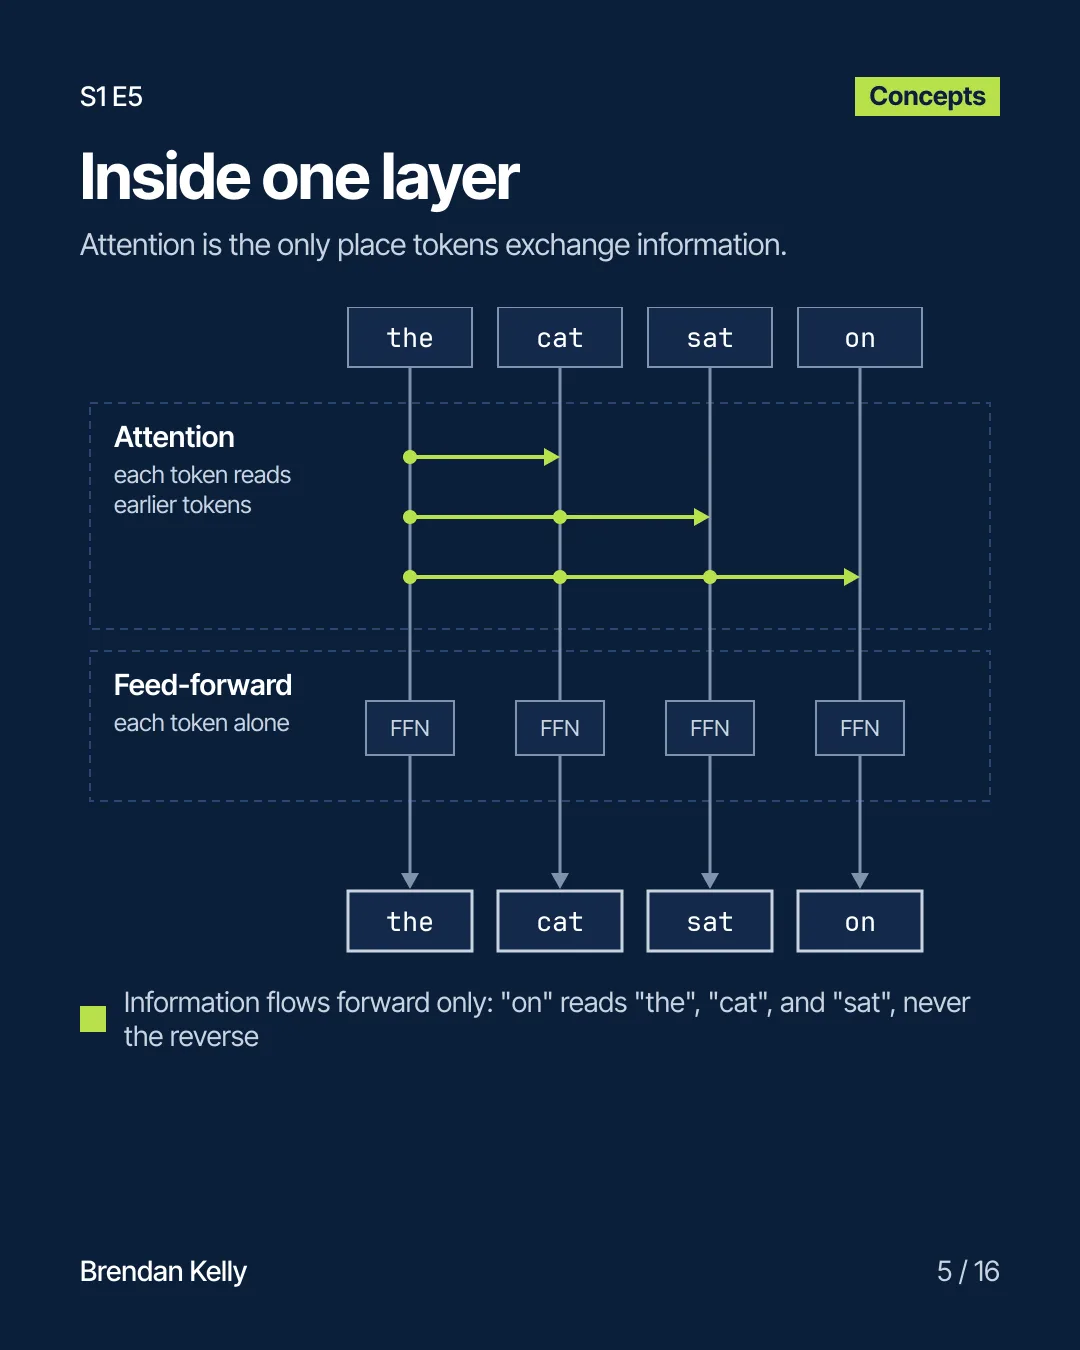
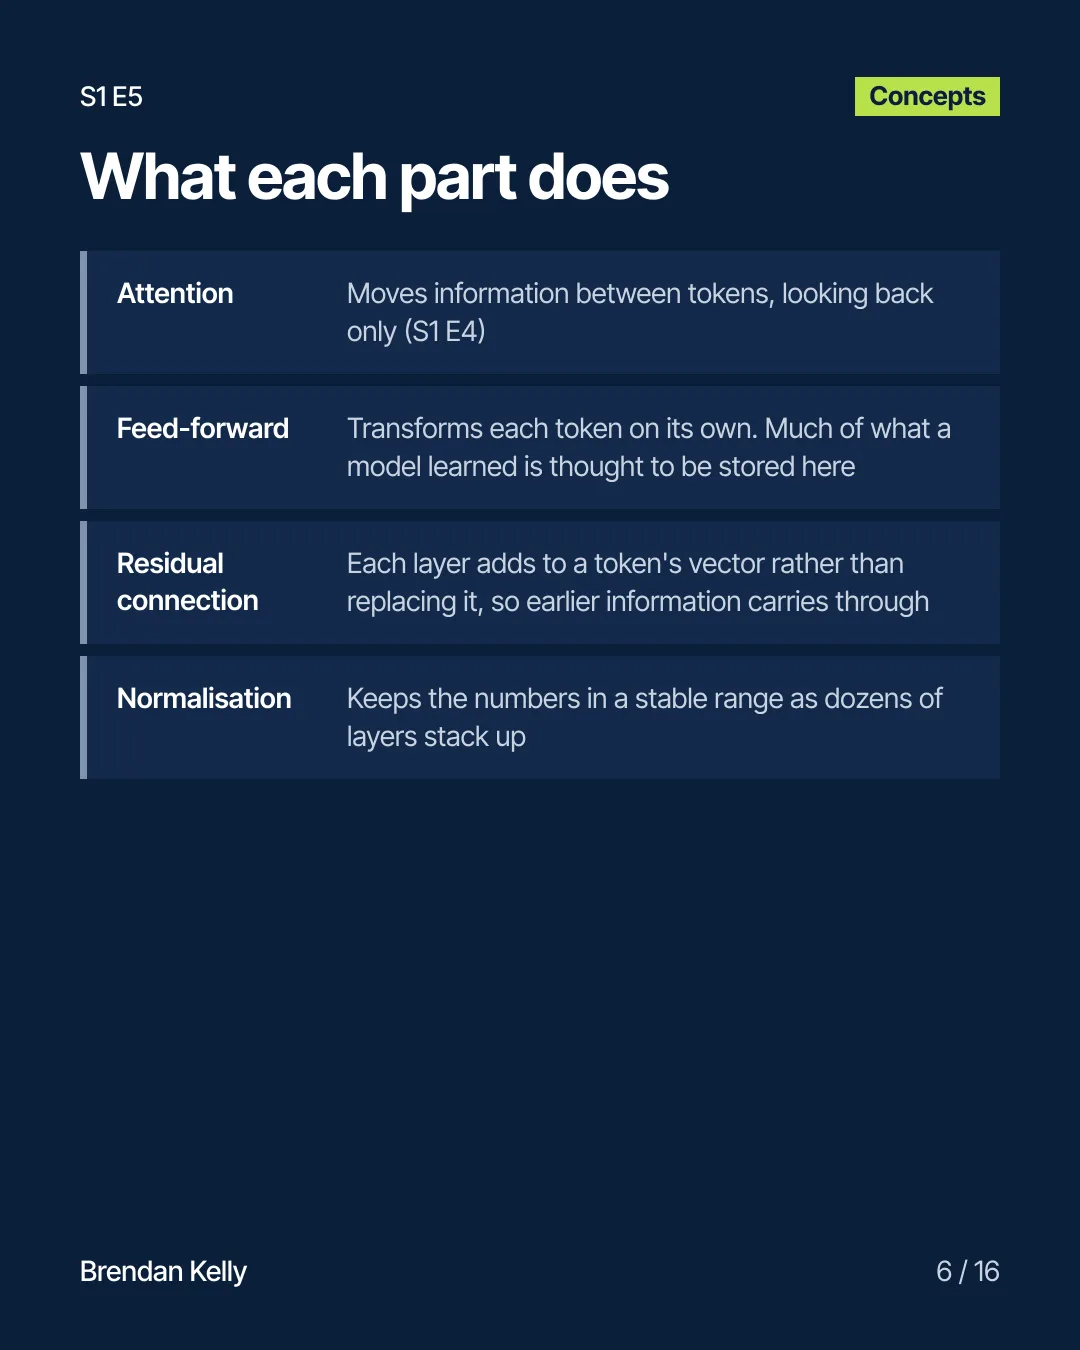
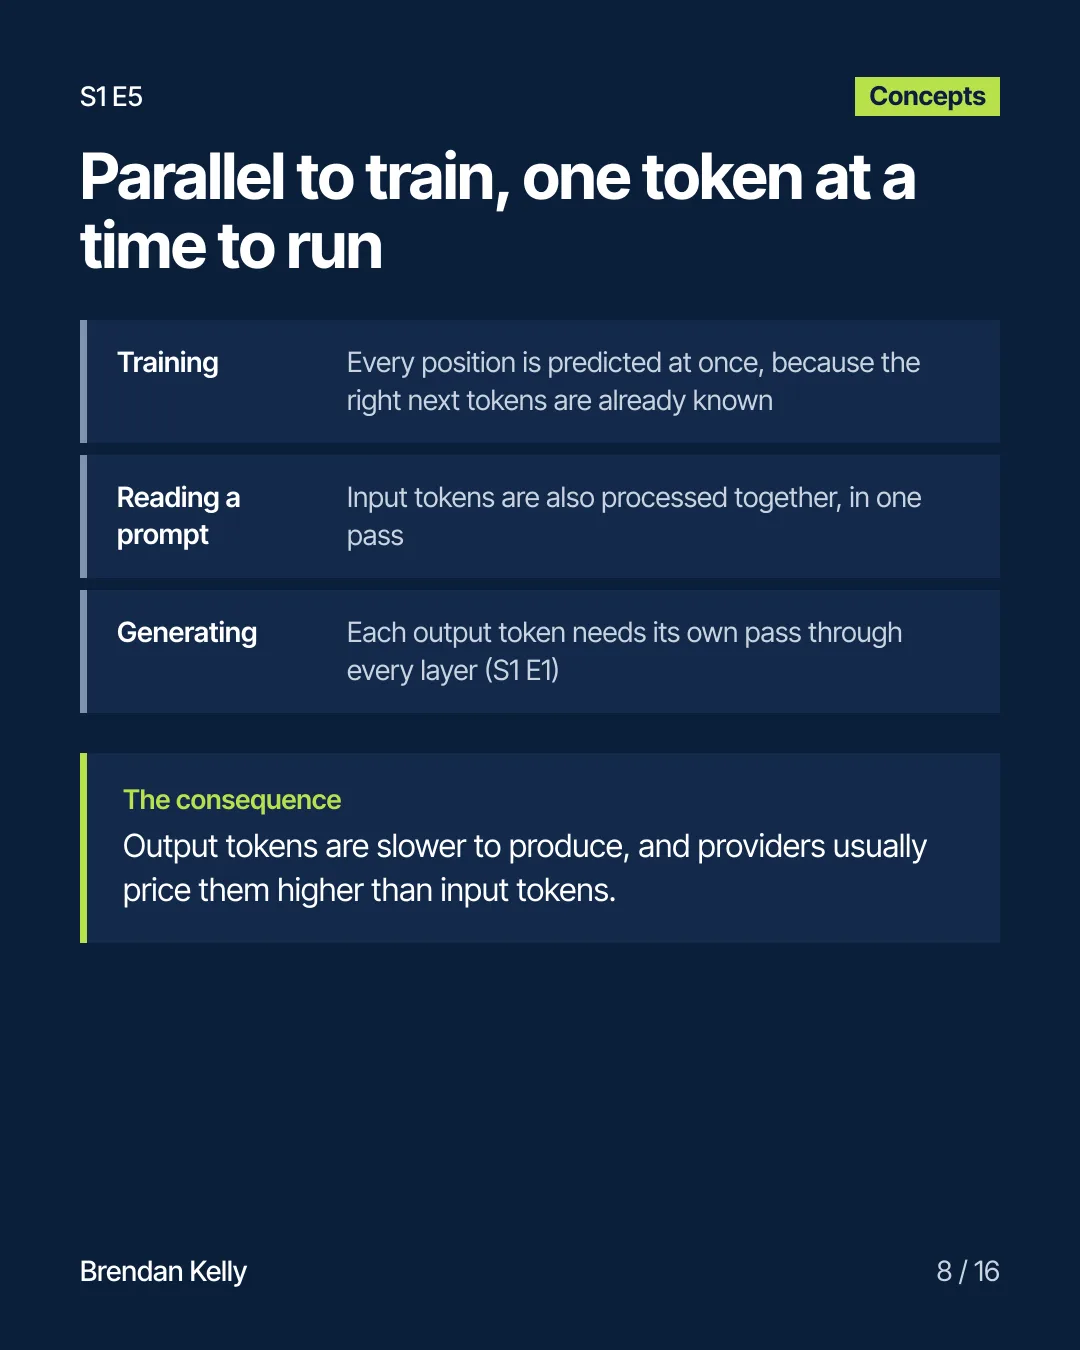
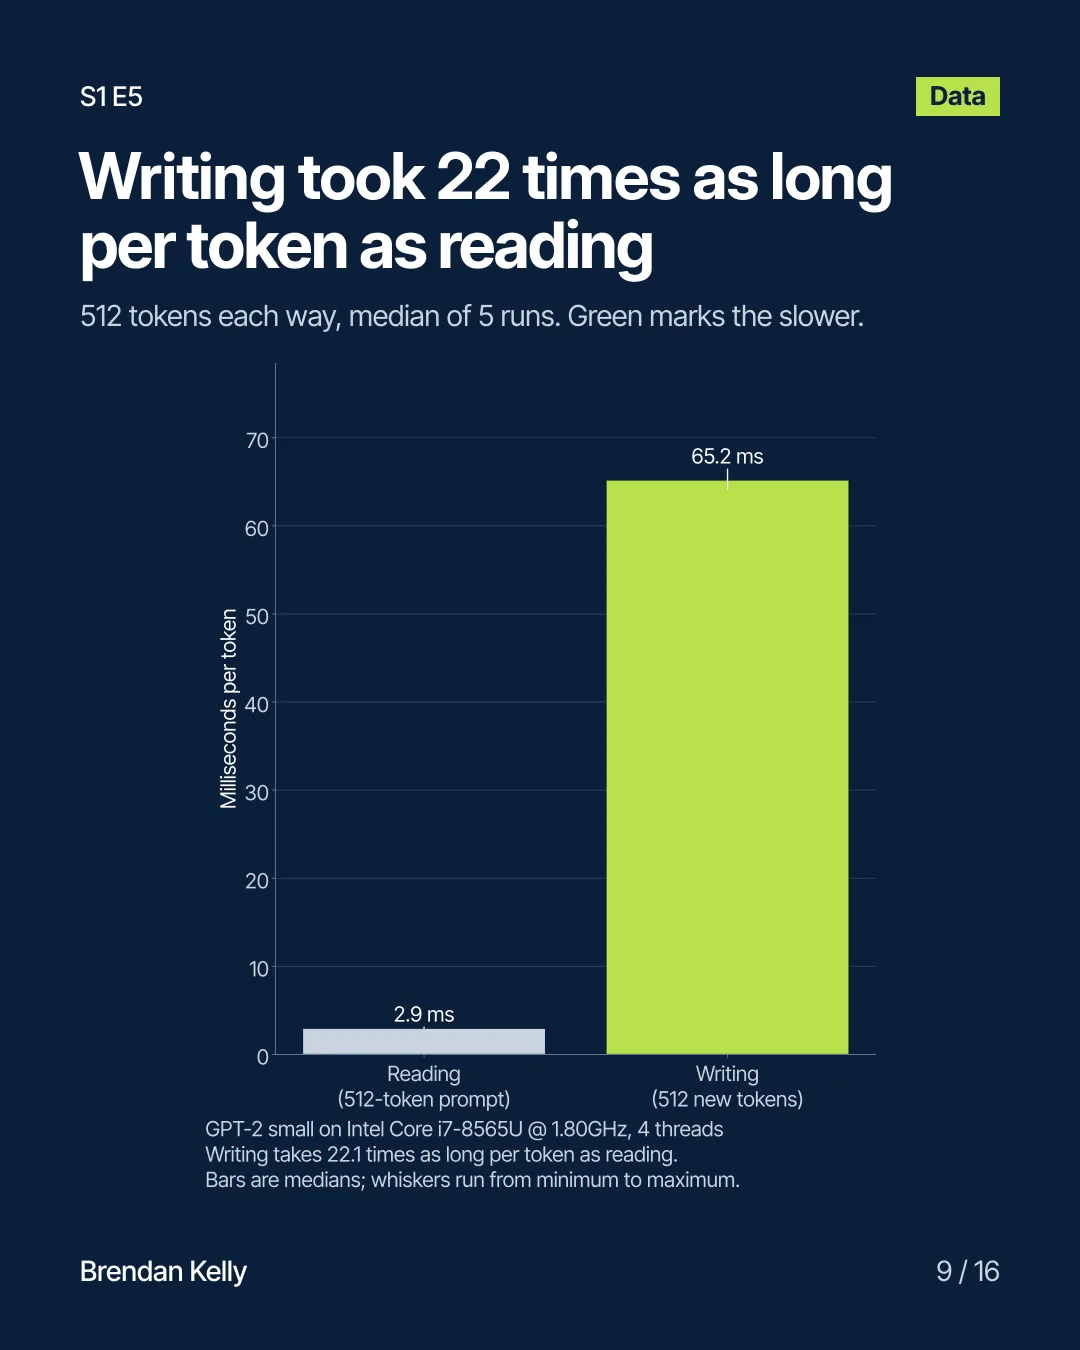
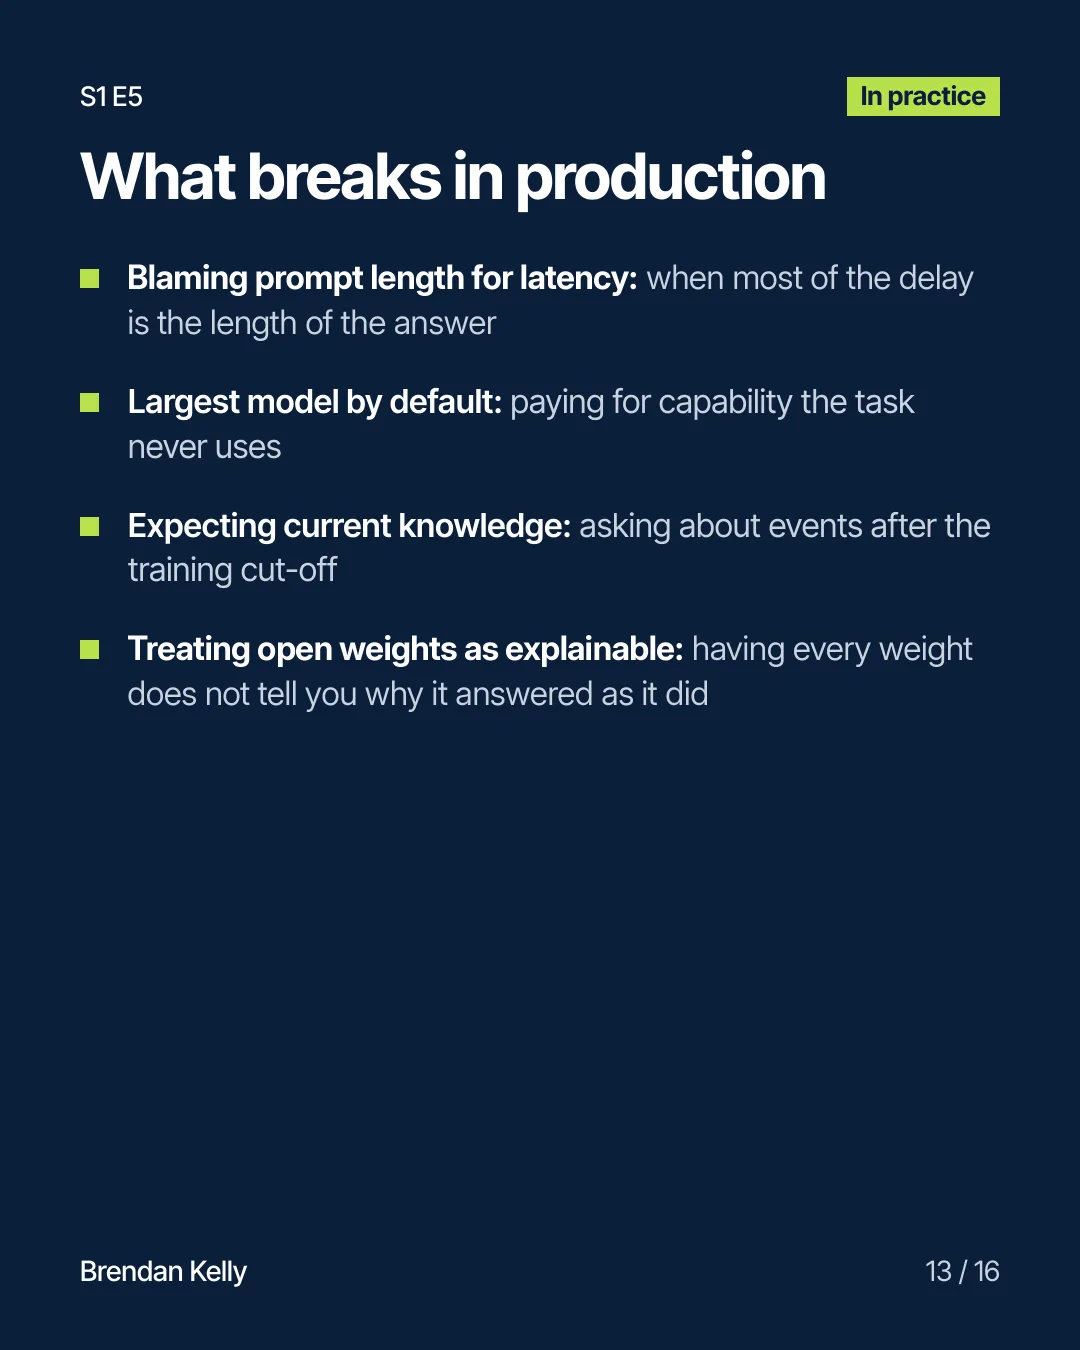
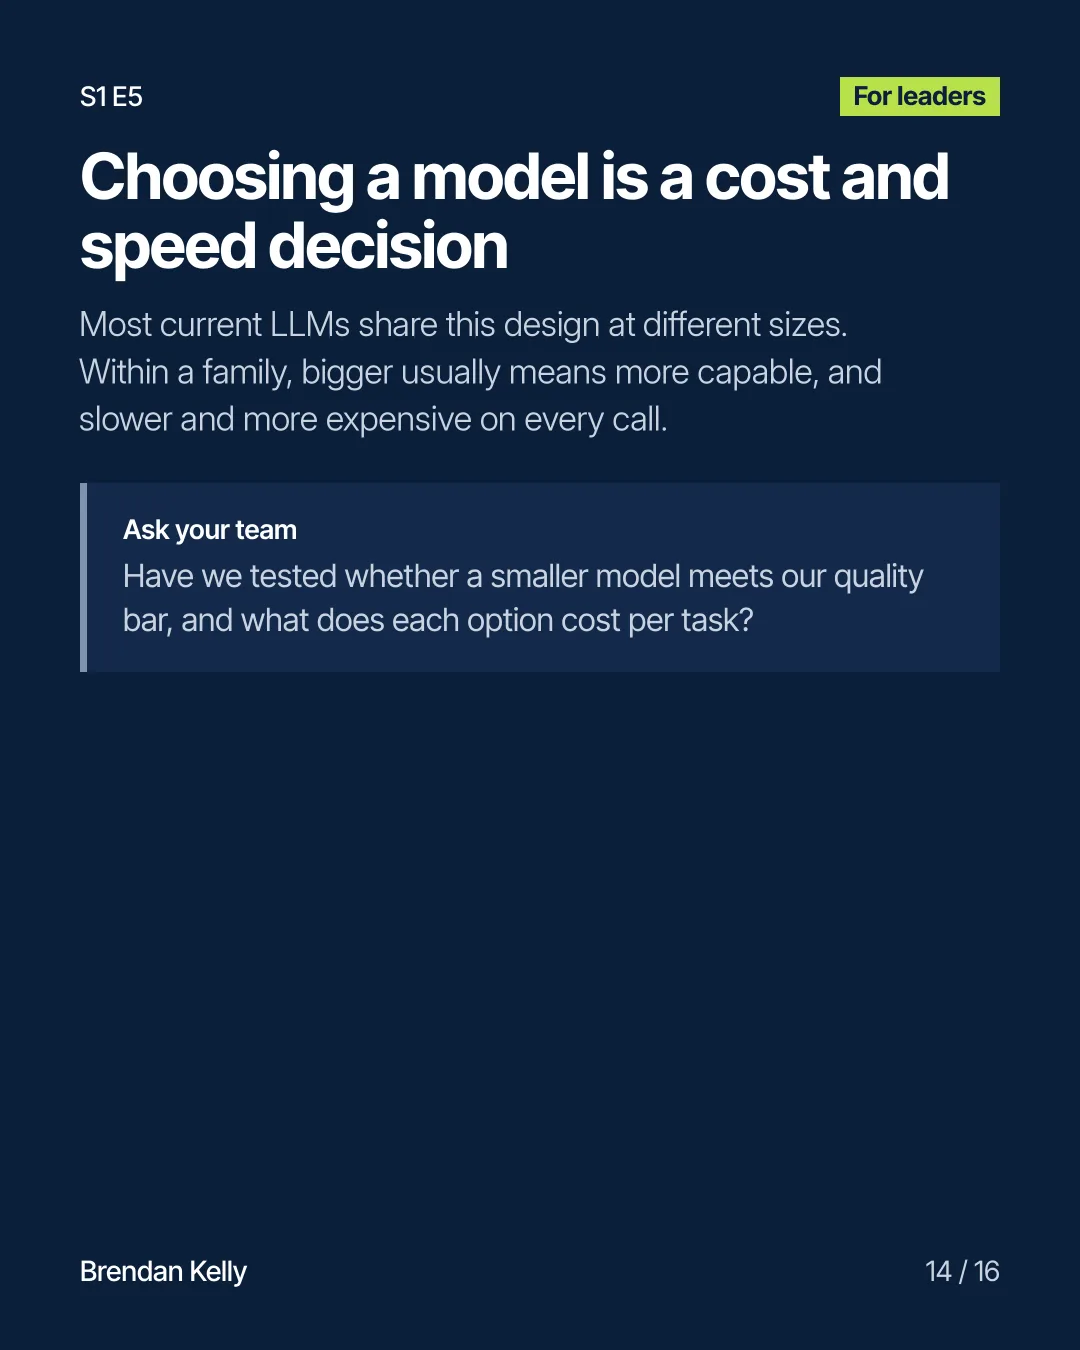
The transformer stacks attention and feed-forward layers over token embeddings, and its shape explains why writing took 22 times as long per token as reading.
Decision rule
Choose the smallest model that passes your own tests, and budget latency on output length.
Ideas in this lesson
- Next-token prediction
- Attention
- Latency